

Karpenter 1.15 node repair: replace-first, until the pool is full
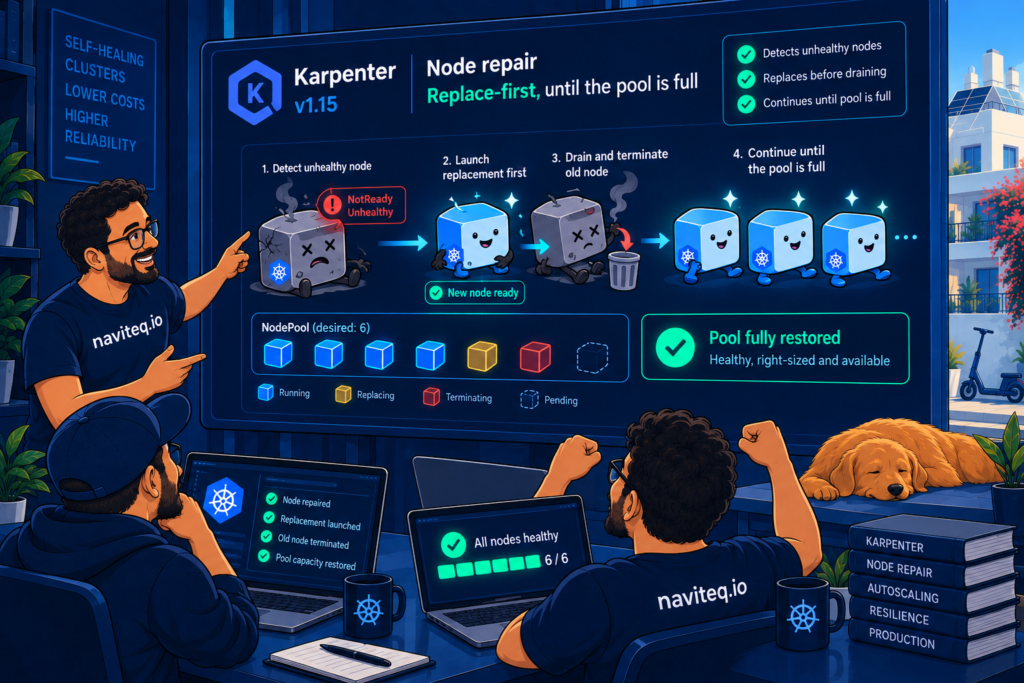
Karpenter 1.15 moves node repair onto the voluntary disruption path, so repair now respects budgets, launches a replacement first and caps the drain. That holds until a NodePool has no room to grow. What changes in your budgets on upgrade, what terminate-first costs on a full reservation, why the 20% breaker is still in the code, and the alerts we would add.
EKS opened up the scheduler. MostAllocated is the one with a bill attached.
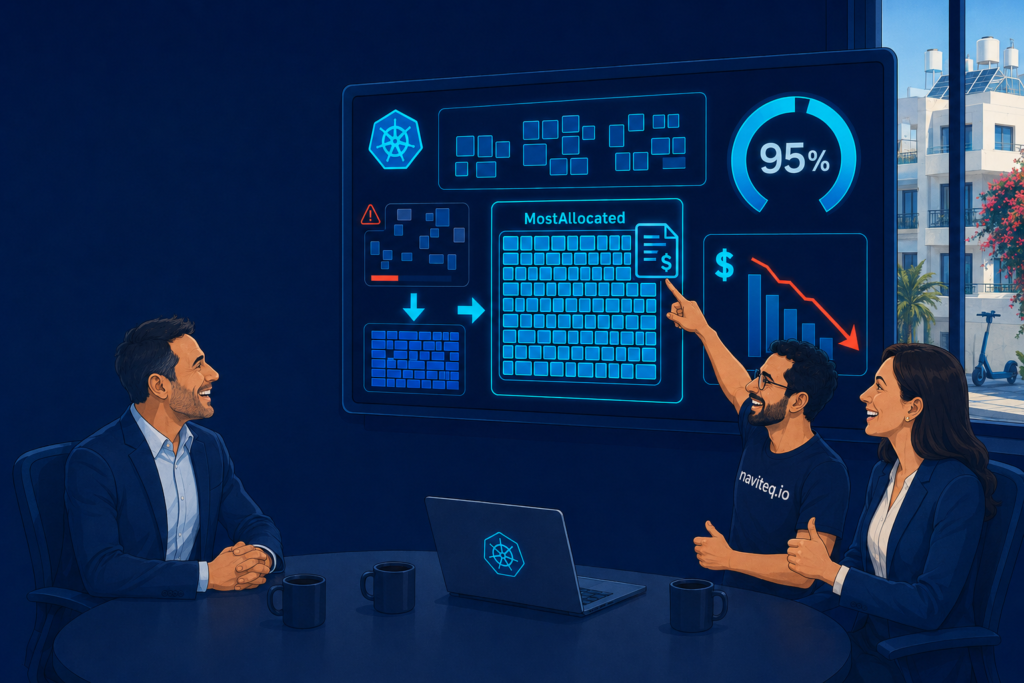
Amazon EKS now lets you set four control plane parameters directly, including the scheduler scoring strategy. Switching from LeastAllocated to MostAllocated packs pods onto fewer nodes and cuts compute spend. The payloads, the resource weights, and the trade-offs that are hard to undo.
Sharing a GPU on EKS: time-slicing, MPS, MIG and DRA
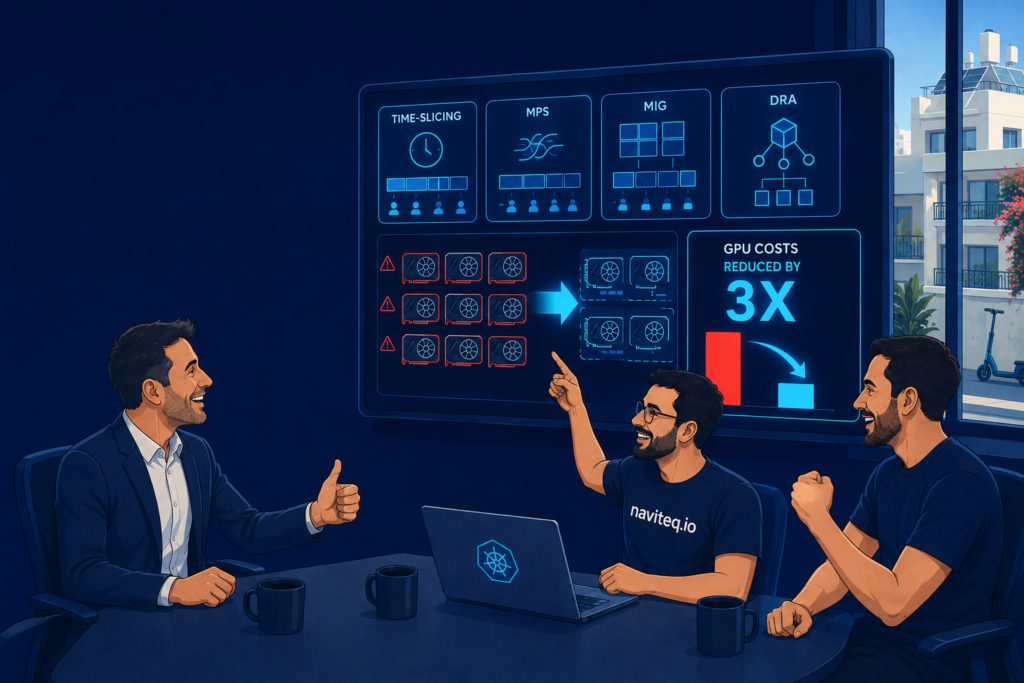
A GPU is billed whole and used in fractions, and Kubernetes gives you four ways to divide one. Time-slicing, MPS, MIG and DRA on Amazon EKS, with the working config for each and the question that decides between them: what does this mechanism actually isolate?
In-place pod resize is GA: rightsizing without the restart
Kubernetes 1.35 made in-place pod resize stable, so CPU and memory on a running pod can change without an eviction. We walk through the config, the pending state that trips up automation, and the workloads this still does not cover.